DGX Station GB300 or GB300 NVL72? Deskside vs. Rack Scale
Both carry the GB300 name. One can sit beside a research team; the other needs a data-center project. Use the actual workload and site plan to decide where to start.
By Uniqcli Team · · 6 min read · Updated
Key takeaways
- Choose Station for local development or a shared lab workload that fits one deskside GB300 system and a site with its required 20 A circuit.
- Choose a GB300 NVL72 rack for sustained multi-GPU training or high-throughput inference when the organization can supply liquid cooling, power, network fabric and operators.
- If Station is too small but a 72-GPU rack is premature, size an eight-GPU server or smaller cluster before committing to either endpoint.
- Station's 748 GB is coherent CPU-plus-GPU memory; NVL72's 20 TB is HBM distributed across 72 GPUs. Neither headline is one GPU's capacity.
On this page
At the Naval Postgraduate School, a DGX GB300 now serves more than 1,500 resident students and 600 faculty working on problems from weather prediction to cybersecurity. NVIDIA's account of the installation names the data platforms, racks, cooling, power work and commissioning behind it. That is a rack purchase. A small research group that needs one large model close to its data may need a DGX Station instead.
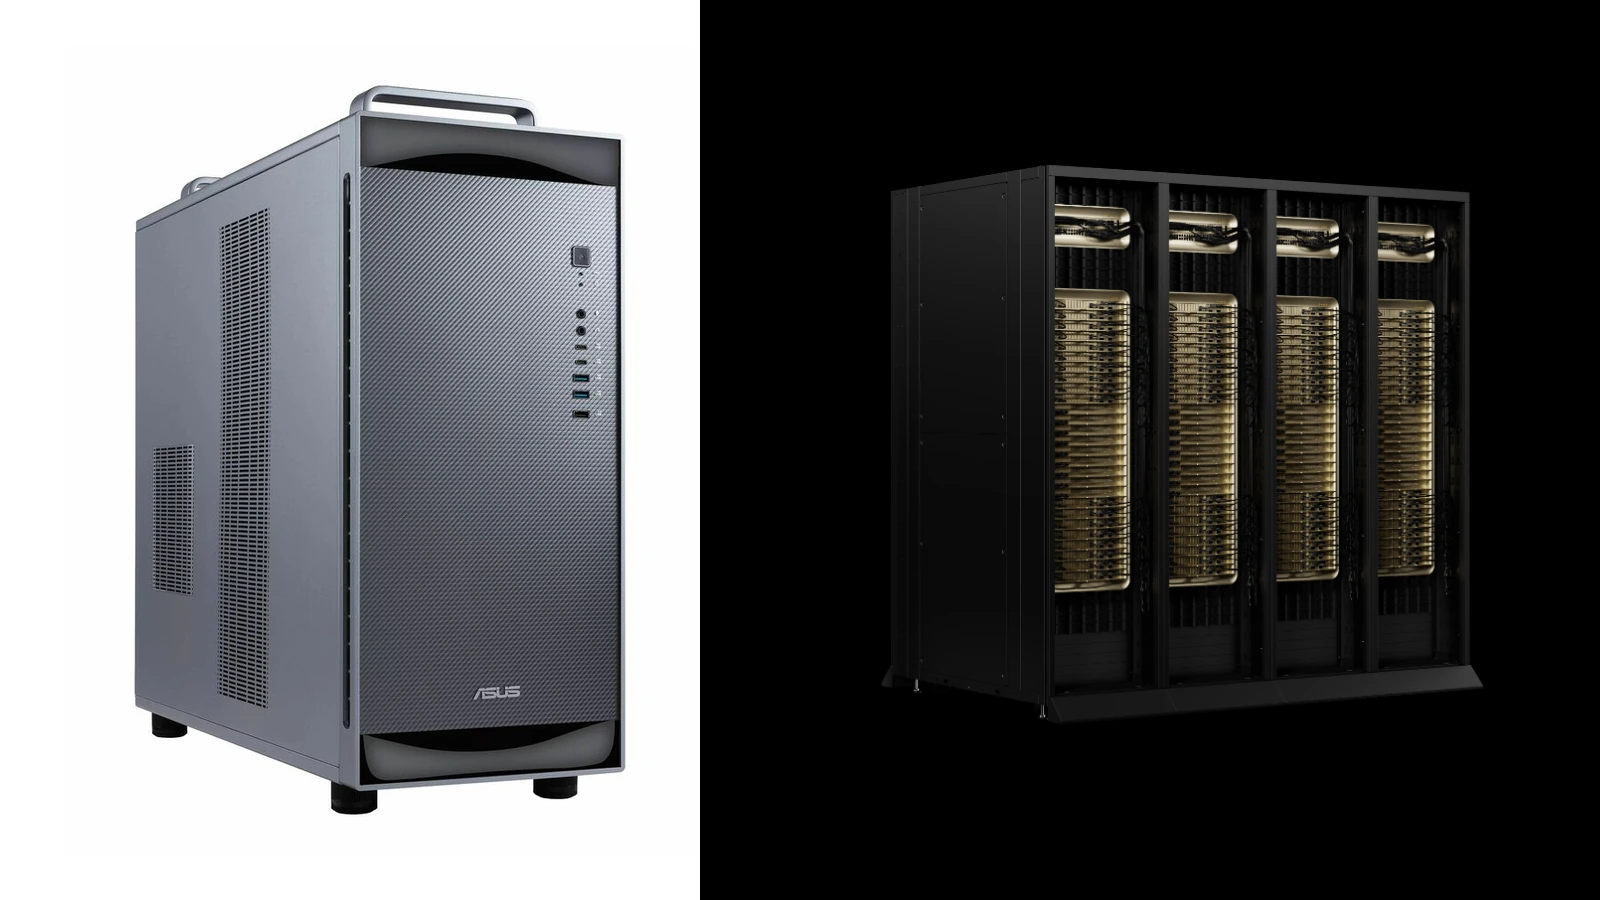
The shared GB300 name makes this an easy comparison to get wrong. Station is a deskside system with one Blackwell Ultra GPU. The DGX GB300 NVL72 is a liquid-cooled rack with 72 GPUs. The decision begins with who will run the system, how often, and what facility can support it.
What is inside each system?
DGX Station places one NVIDIA Blackwell Ultra GPU beside a 72-core Grace CPU in a deskside chassis. NVIDIA lists 252 GB of HBM3e GPU memory and 496 GB of LPDDR5X CPU memory, connected through NVLink-C2C. Its published peak is up to 20 PFLOPS of FP4 Tensor Core performance, with the usual precision and sparsity qualifications. NVIDIA positions it for large-model development, local inference, data science, and agent workflows. It can also serve several developers as a local compute node; NVIDIA lists support for up to seven Multi-Instance GPU partitions.
NVIDIA DGX GB300 is a different scale of infrastructure. NVIDIA lists 72 Blackwell Ultra GPUs, 36 Grace CPUs, 20 TB of aggregate GPU memory, and 37 TB of total fast memory for the liquid-cooled rack. Its NVLink switch system links the GPUs inside the rack. The system targets training, post-training, and inference at AI-factory scale. The rack also needs an appropriate fabric and operations plan if it will connect to other racks, storage, or users.
Read the memory figures correctly
The Station's 748 GB is a coherent CPU-and-GPU system memory figure. It does not mean the Station has 748 GB of HBM on its GPU. Its GPU HBM3e capacity is 252 GB; the other 496 GB is Grace CPU memory. Coherence lets software work across the two memory types, while their bandwidth and behavior still differ.
The NVL72 rack's 20 TB is GPU HBM aggregated across 72 GPUs. NVIDIA separately lists 37 TB of total fast memory when CPU memory is included. That aggregate is useful for distributed workloads, but it should not be described as the HBM capacity of a single GPU or compared directly with one Station's coherent memory as though both figures represent the same resource.
For either system, model parameter count alone is a weak sizing rule. Precision, quantization, context length, batch size, fine-tuning method, and the number of simultaneous users all affect memory and throughput. NVIDIA says DGX Station supports models up to 1 trillion parameters; validate the proposed model and workflow before treating that ceiling as a performance guarantee.
Choose by workload and deployment boundary
Choose a DGX Station path when the workload fits one deskside system and a small team needs local prototyping, fine-tuning or inference without waiting for shared cluster time. If several people will use it, define access and scheduling; MIG partitions share one GPU rather than multiplying it. An additional RTX PRO GPU is an OEM-dependent visualization and simulation option, not another GB300 accelerator.
Choose the DGX GB300 rack path when the requirement is sustained, large-scale training or high-throughput inference and the organization is prepared to run rack-scale AI infrastructure. The NVL72 architecture is an integrated, liquid-cooled system, so the purchase includes decisions about facility power, cooling distribution, network fabric, storage, operations software, commissioning, and service ownership. A rack quote that covers only compute hardware is incomplete.
If one Station misses the memory or throughput target but a rack is not justified, compare an eight-GPU DGX server or a smaller cluster. That middle path still needs networking, software and operations planning, but it does not presume the full NVL72 facility project.
What a real rack project includes
NVIDIA says the Naval Postgraduate School commissioned its DGX GB300 in July 2026 for campus research and instruction. DDN and VAST provided data infrastructure. Vertiv supplied racks, cooling and power infrastructure and supported installation sequencing, testing, commissioning and fluid management. That list is more useful to a prospective rack buyer than comparing theoretical PFLOPS with a workstation.
You do not need the same partners or campus scale. You do need owners for the same categories: data path, liquid cooling, electrical supply, network fabric, deployment sequence, acceptance testing and long-term operations. If those owners are not yet identified, a rack quote is still a design exercise.
Check the site before comparing quotes
NVIDIA lists 1,600 W total system power and a 20 A circuit requirement for DGX Station. Confirm the exact OEM configuration, circuit, plug, room ventilation, floor placement, network connection, and delivery route with the site team. These checks are smaller than a data-center build, but they still affect whether the machine can be installed and used on arrival.
For the DGX GB300 rack, involve facilities and data-center operations before a commercial quote is finalized. Ask for the rack's electrical design envelope, liquid-cooling interfaces and capacity, residual air-cooling load, floor and receiving requirements, network topology, storage path, and commissioning plan. NVIDIA describes the system as a liquid-cooled rack-scale platform; a standard air-cooled server row should not be assumed sufficient.
Review the two buying paths
The following pages identify concrete paths for discussing each system. Use the exact proposed configuration and current manufacturer documentation for the final technical review.
ASUS DGX Station architecture workstation
A catalog example of a GB300 deskside system. Request confirmation of configuration, software, support, and current availability.
HPE GB300 NVL72 rack system
A rack-scale path that needs an engineered quote covering compute, fabric, facility readiness, deployment, and support.
Uniqcli lists deskside Station-architecture systems from ASUS and MSI. The MSI entry is a barebones, request-pricing configuration; neither product card represents the 72-GPU rack. Use the HPE rack path above for an engineered GB300 NVL72 discussion.
Deskside Station systems we list
ASUS Computer International
Asus ExpertCenter Pro Agent Computer PRO ET900N G3-2SSD Workstation
$114,628.43Back-orderedMSI
MSI XpertStation WS300 NVIDIA DGX Station GB300 748GB Deskside AI…
$105,451.75Back-ordered

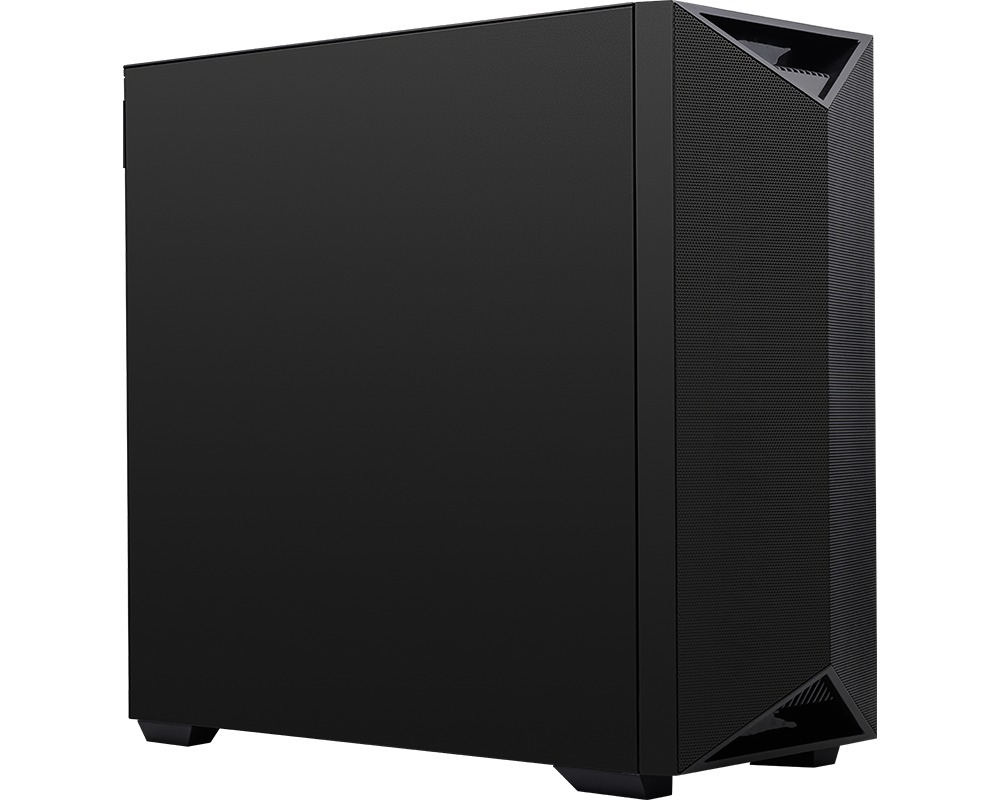
These are Station-class products, not NVL72 racks. Confirm the MSI build contents and request a separate rack-scale project quote.
Send a useful quote request
For a Station, share the intended models and frameworks, whether the system is dedicated or shared, data location, storage requirement, software and support expectations, site power, quantity, and desired installation date. If RTX PRO visualization is required, state that explicitly so the supported OEM configuration can be checked.
For an NVL72 rack, add expected training and inference workloads, target throughput and concurrency, existing network and storage designs, facility power and cooling information, receiving constraints, security requirements, and the team that will operate the system. A quote can then define the full deployment boundary rather than only the accelerator count.
Request a configured DGX quote
Tell us whether you are planning a deskside system or a rack deployment, and send your workload, user count, site requirements, and target timeline. We can scope the configuration and confirm current availability and support.
FAQ
Can our facility accept a GB300 NVL72 rack?
Only a site review can answer that. Ask facilities and the rack supplier to check electrical capacity and distribution, liquid-cooling supply and return, residual room heat, floor loading, delivery path, network paths and service clearance. A standard air-cooled rack space is not enough evidence.
What sits between one Station and a 72-GPU rack?
An eight-GPU DGX server or a smaller cluster is the comparison to request when one Station is insufficient but NVL72 scale or liquid-cooling work is not justified. Size that middle option with the same model, precision, concurrency and throughput target used to judge Station; it still needs a fabric, storage path and an operations owner.
When is one DGX Station enough for a team?
When representative models fit at the required precision and context, users can share the system without missing latency or throughput targets, and the site can supply its 20 A circuit and cooling. NVIDIA lists up to seven MIG partitions, but usable concurrency still needs testing with the team's jobs. A pilot is cheaper than sizing by a memory headline alone.
Is the rack's 20 TB of GPU memory available to one process?
It is aggregate HBM across 72 GPUs. Distributed software has to place model weights and move data across the rack. Ask for a measured run of the actual model and framework rather than treating aggregate memory as one GPU address space.
Sources
- 1.NVIDIA DGX Station product specificationsnvidia.com— Deskside architecture, coherent memory breakdown, workloads, power, and supported expansion.
- 2.NVIDIA DGX GB300 product specificationsnvidia.com— Rack architecture, GPU count, aggregate memory, and liquid-cooled positioning.
- 3.NVIDIA GB300 NVL72 platform specificationsnvidia.com— Rack-scale NVLink, memory, and network details.
- 4.NVIDIA Naval Postgraduate School DGX GB300 installationblogs.nvidia.com— A real research deployment and its data, cooling, power and commissioning partners.
- 5.MSI XpertStation WS300 manufacturer specificationseps.msi.com— Station-architecture barebones configuration.
Product specifications reviewed October 25, 2026. Confirm the current OEM configuration and site requirements before ordering.