Check surviving pool capacity against request rate and concurrency under explicit node-loss and utilization assumptions.
Networking
N+1 server pool capacity
Check surviving pool capacity against request rate and concurrency under explicit node-loss and utilization assumptions.
Example inputs · Replace these with your measurements to build your plan.
Method, example and sources
Convert concurrency and mean service time into a second per-node rate bound.
Use the tighter entered request-rate or concurrency constraint.
Apply usable utilization and remove the unavailable nodes.
Round required healthy nodes upward and add the failure allowance.
Worked example. At 3,000 RPS per node and 70% usable load, five healthy nodes cover 10,000 RPS. One unavailable node makes six deployed nodes the modeled minimum.
Identical nodes share requests evenly. The tighter of service rate and concurrency bounds the pool.
Required nodes including failures
6
Surviving nodes
5
Usable surviving capacity
10,500requests/s
Mean in-flight requests
1,000
Little's law uses the entered mean service time under a stable workload; tail latency and queue growth require a benchmark. Session affinity, unequal weights, retries, dependencies and health-check failover delays are outside this model. Zero traffic with zero healthy nodes does not demonstrate availability.
From the catalog
Servers
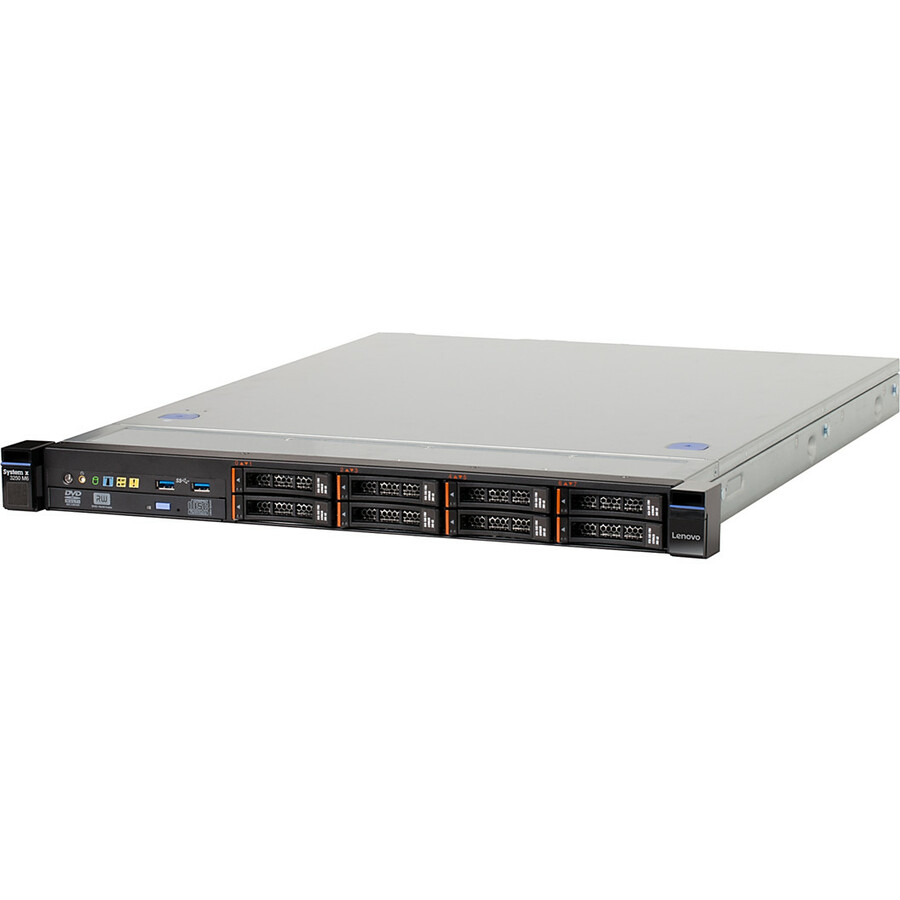
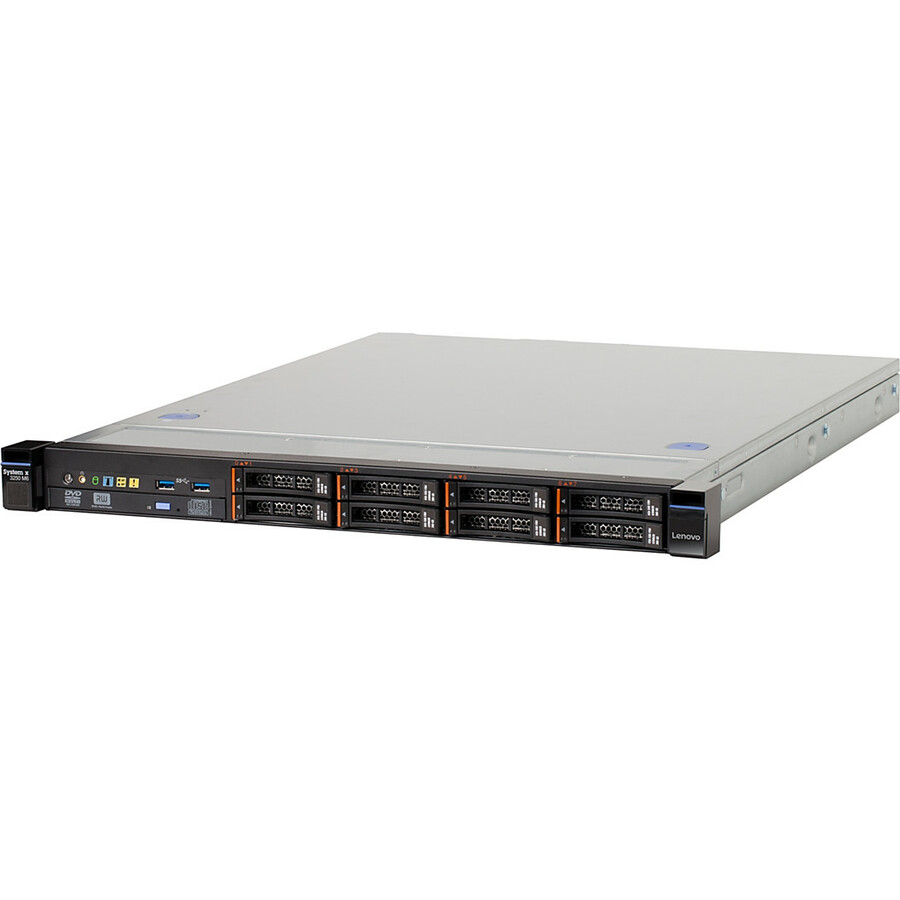
Explore related listings, then confirm the exact model requirements against your plan. These listings are not an automatic compatibility or capacity verdict.
Redundancy only helps when the surviving nodes can carry the workload. This worksheet removes the failed nodes before comparing capacity, rather than spreading load across machines that no longer exist. A second concurrency bound uses mean service time, which can expose an application limit even when a headline requests-per-second figure looks sufficient.
What to verify next
The model assumes identical healthy nodes and even balancing. Sticky sessions, uneven weights, database limits, retries and slow health detection can make failover less favorable. Mean service time does not describe tail latency near saturation. Use a workload-specific benchmark and an observed failure exercise before accepting a final server count or claiming an availability target.
Worked example
At 3,000 RPS per node and 70% usable load, five healthy nodes cover 10,000 RPS. One unavailable node makes six deployed nodes the modeled minimum.